Blog
Thirteen Rows, One Ratio: Why Every anthropic models Row Prices Output at Exactly Five Times Input

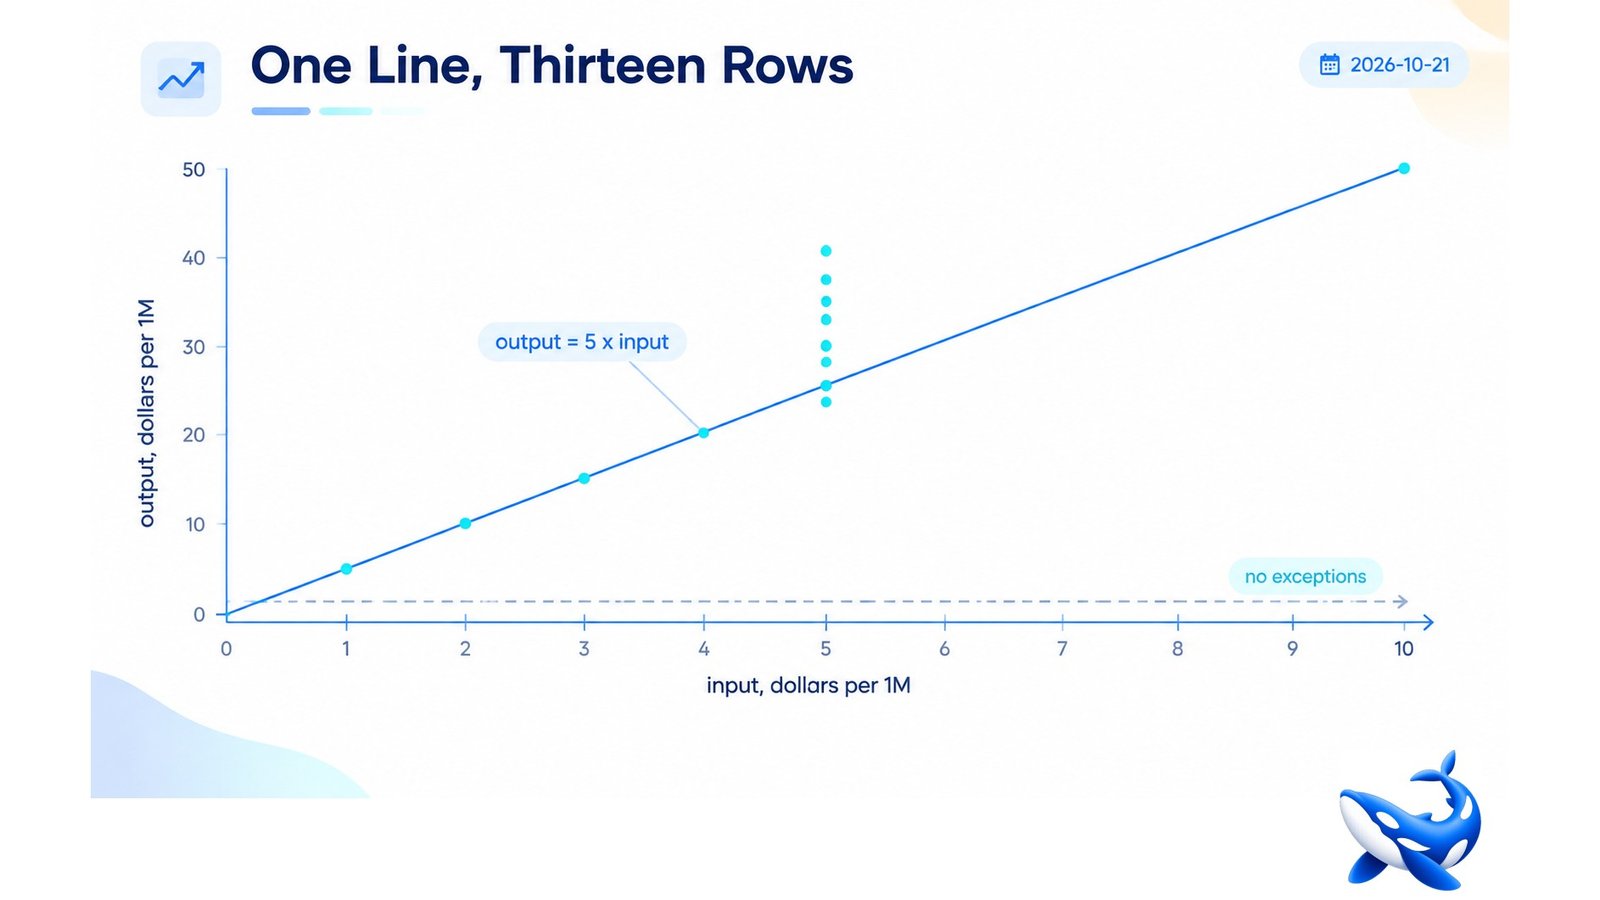
Divide the output rate by the input rate on every row of the OrcaRouter anthropic models page and the same number comes back thirteen times.
$5.00 and $25.00. $10.00 and $50.00. $2.00 and $10.00. $4.00 and $20.00. $3.00 and $15.00. $1.00 and $5.00. Every pair divides to 5.00 [VENDOR: the provider’s published rates, passed through with $0 markup], and there is no exception in the catalogue — not on the two older 200K models, not on the flagship, not on the cheapest row.
No other catalogue on the site behaves this way. The OpenAI page spans 1.00 to 20.00 across its rows; the Qwen page 3.00 to 11.67; Z.ai 3.14 to 5.50; DeepSeek 3.00 to 4.00 [OURS]. A constant ratio across a whole provider is a design decision, and unpacking it is more useful than the number itself.
What a constant output ratio does to a comparison
The practical effect is that one number tells you the whole rate card. Name the input price and the output price follows: $6.00 in means $30.00 out, $7.50 means $37.50. Two of the five rate dimensions collapse into one, which makes this the easiest catalogue in the set to hold in your head and the hardest to accidentally misread.
It also means input price and output price can never disagree about which model is more expensive. On a catalogue with variable ratios, a row can be cheaper on input and dearer on output, and the “cheaper” label depends on your workload’s shape. Here it never does: Opus 5.5 at $4.00/$20.00 is cheaper than Fable 5.1 at $10.00/$50.00 on both columns, and cheaper than Opus 5 at $5.00/$25.00 on both, and there is no workload mix that flips the order.
The corollary is that a five-to-one ratio makes the output line dominant in almost any realistic workload. A million tokens of traffic at a typical 70/30 input/output split spends 30 percent of its volume on a line that is five times as expensive. Do the arithmetic on the Opus 5.5 row: 700,000 input tokens at $4.00 per million is $2.80; 300,000 output tokens at $20.00 is $6.00. Output is 68 percent of the bill on 30 percent of the tokens.
At a one-to-one ratio those two terms would be equal for the 70/30 split at equal rates; at five-to-one the output line is more than twice the input line, and every decision that shortens the answer saves roughly twice as much per token as the equivalent decision that shortens the prompt.
The catalogue’s three blocks
Read the thirteen rows as a price ladder and they sort into three blocks, all of them maintaining the ratio.
The $10 / $50 block. Claude Fable 5 and Fable 5.1, both quality 10 on the page’s own composite [OURS]. Two rows at the top of the ladder, identical rates, identical context and output limits, differing only in cached-input price — $1.00 against $0.250.
The $5 / $25 block. Opus 4.7, 4.8, 5 and 4.6, four rows at one rate. All four carry 1M context and 128K max output. Three score 10 and one scores 9.
The $2–$4 block. Sonnet 5 and 5.5 at $2.00/$10.00, Opus 5.5 at $4.00/$20.00, Sonnet 4.6 and Opus 4.5 at $3.00/$15.00, Sonnet 4.5 at $3.00/$15.00, Haiku 4.5 at $1.00/$5.00.
Within each block the prices are identical and the rows are separated by something else: cached rate, context window, output ceiling, quality score. That is the shape of a mature catalogue — the price is a tier label and the differentiation lives in the other columns. A reader who ranks these rows by price has ranked them into three groups and learnt nothing about which one to use.
The two columns that do separate the $5 block
Four Opus rows at $5.00/$25.00 is the clearest test of that idea.
| Row | Cached | Context | Max out | Quality |
| Claude Opus 4.5 | $0.500 | 200K | 64K | 8 |
| Claude Opus 4.6 | $0.500 | 1M | 128K | 9 |
| Claude Opus 4.7 | $0.500 | 1M | 128K | 10 |
| Claude Opus 4.8 | $0.500 | 1M | 128K | 10 |
Four rows, one rate card, and the envelope widens from 200K/64K to 1M/128K between the oldest and the rest. The quality score climbs 8 → 9 → 10 → 10 across the same span.
Everything about the price is identical; everything about the product is not. That is what a rate card looks like when the vendor has decided that model generation is not a pricing dimension — the same dollars buy a bigger window and a higher score, and the customer’s decision is entirely about capability rather than cost.
It also means the $5 block contains a latent upgrade: a workload sized against Opus 4.5’s 200K window has five times the room on 4.6 and later at the identical rate. That is the sort of migration a price comparison will never surface, because the prices do not differ.
What the ratio does not tell you
A constant output-to-input ratio says nothing about absolute cost, and the temptation to read it as a discount is worth heading off.
Five-to-one is not generous or stingy on its own. It is a ratio between two rates that both move with the model. Fable 5.1’s output at $50.00 per million is ten times Opus 5.5’s input at $4.00, and both figures are true at once because they describe different rows. The comparison that matters is between rows, not between columns.
The ratio is also not a statement about how many tokens a model emits. Two models at five-to-one can produce wildly different answer lengths for the same prompt, and on a fixed budget the chattier model costs more per task even at identical rates. The page cannot tell you that; only your own traffic can.
And the ratio says nothing about the cached rate, which is the one place this catalogue does diverge — eleven rows at ten percent of input, one at five, one at two and a half [OURS]. A model that is uniform on the output ratio is not uniform on the cache ratio, and the cache ratio is what determines the cost of a repeated prefix.
How to use a uniform rate card
Four habits, all of which fall out of the constant ratio.
Learn one number per row. Input price is the key and output is five times it. That halves the arithmetic in any comparison and removes the class of error where a cheap-input row turns out to be an expensive-output one.
Rank by envelope, not by price. With the ratio constant, price only tells you the tier. The columns that decide fitness are context, max output and the quality composite — and on this catalogue they vary within a tier by as much as five times on context.
Model the output share first. A five-to-one ratio makes the answer the dominant cost term. Before tuning anything else, estimate how many output tokens a task actually needs; a 20 percent cut in answer length is worth more than most input-side optimisations.
Read the cache column separately. It is the one column not governed by the rule, and the two rows that break the ten-percent pattern are the two newest additions — which is where a stale assumption will bite first.
A rate card that repeats one ratio thirteen times is easier to read than it looks, provided you stop reading it as a list of prices and start reading it as three tiers with four differentiating columns. The price tells you which tier; the rest of the table tells you whether the tier is the right one.
Sourcing note: every rate, context window, max-output value and cached-input price quoted here is read from the OrcaRouter Anthropic provider page on 2026-10-21, where the rates are the provider’s published prices passed through with $0 markup [VENDOR]. The observation that all thirteen output-to-input ratios are exactly 5.00, the three-block reading, the cross-provider ratio ranges and the monthly arithmetic are ours [OURS]. The 0-to-10 quality scores are our own composite, not a third-party benchmark. No third-party evaluation figures are used. Rates change; all values checked 2026-10-21.

Can Machines Spot Machine Writing? A Closer Look at AI Essay Checkers

How Niche eCommerce Founders Can Validate Product Demand Before Investing in Inventory

Building a Competitive Online Presence with Link Building Services and SEO Packages

Luxury Rigid Boxes: Planning Premium Packaging Around Product Fit and Presentation

Tommy Bynes: Everything About Amanda Bynes’ Brother

How to Cook Healthy Family Meals Safely: A Parent’s Guide

How Personalized Addiction Treatment Plans Can Improve Patient Engagement and Recovery Outcomes

Need LLC Help? Here’s How to Get an LLC Online

Helen Beth Duntz: The Real Story of James MacArthur’s Wife

Cassandra Marino: The Full Story of Caitlyn Jenner’s Eldest Daughter

Charfen.co.uk: What Is It and What Does It Offer?

SoSoActive: Everything You Need to Know About the Digital Platform

Buying Property Through Your Super? Run an SMSF Loan Calculator Before You Call a Broker

Kerri Browitt Caviezel: Everything to Know About Jim Caviezel’s Wife

Voozon.com: Everything You Need to Know Before Using It

From Search Visibility to Enquiries: Building a Stronger SEO System in Essex

Eractoll: What Is It and Why Did Enterprise Charge You?

How to Make Kofta Kebabs at Home Without Overthinking It

Michele Morrone Net Worth: His Salary, Earnings, and Rich Life

NF Net Worth: How the Rapper Turned Pain Into Millions
Can Machines Spot Machine Writing? A Closer Look at AI Essay Checkers
How Niche eCommerce Founders Can Validate Product Demand Before Investing in Inventory
Building a Competitive Online Presence with Link Building Services and SEO Packages
Luxury Rigid Boxes: Planning Premium Packaging Around Product Fit and Presentation
Tommy Bynes: Everything About Amanda Bynes’ Brother
How to Cook Healthy Family Meals Safely: A Parent’s Guide
How Personalized Addiction Treatment Plans Can Improve Patient Engagement and Recovery Outcomes
Need LLC Help? Here’s How to Get an LLC Online
Helen Beth Duntz: The Real Story of James MacArthur’s Wife
Cassandra Marino: The Full Story of Caitlyn Jenner’s Eldest Daughter
-
 News2 months ago
Who Is Gigi Yallouz? Meet Owain Yeoman’s Wife and Jewelry Designer
-

 News2 months ago
Who Is Tove Torvalds? All About Linus Torvalds’ Wife
-
 News2 months ago
Rajesh Nihalani: What We Know About Archie Panjabi’s Husband
-
 News2 months ago
Stephan Farmiga: Everything to Know About Vera Farmiga’s Brother